NVIDIANew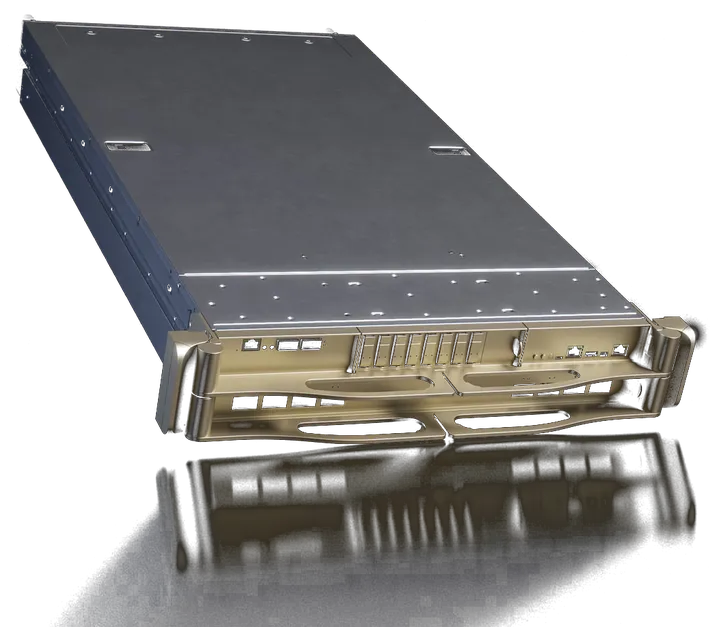
GPU & AI Servers
NVIDIA DGX Rubin NVL8
Liquid-cooled DGX system for training, post-training and inference across every AI workload.
- GPUs: 8× NVIDIA Rubin
- Interconnect: Sixth-generation NVLink
- Cooling: Liquid-cooled
Eight Rubin GPUs on sixth-generation NVLink — the building block for partner servers from Supermicro, ASUS and others.
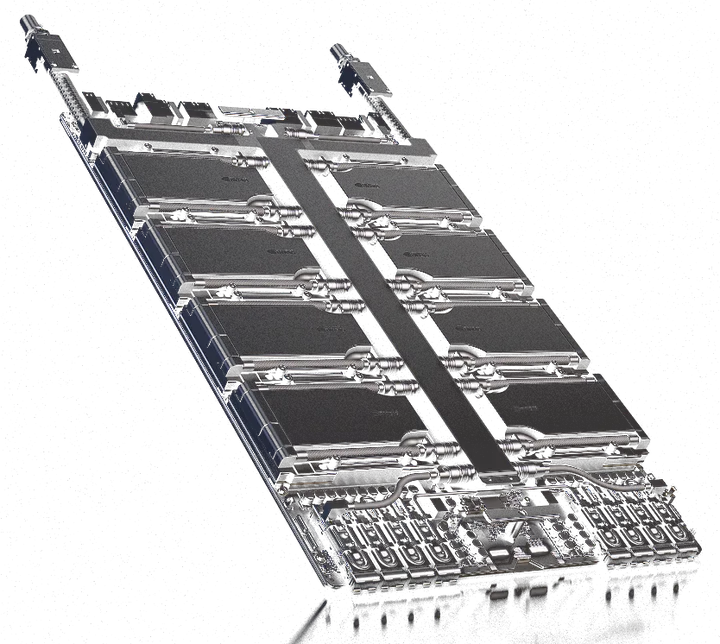
NVIDIA HGX Rubin NVL8 is an eight-GPU baseboard that links Rubin GPUs with sixth-generation NVLink. Server makers build it into their own systems, so you can choose the chassis, cooling and CPU platform that fits your data center.
NVIDIA rates HGX Rubin NVL8 at 10x the token throughput of HGX B200, and at matching training performance with 4x fewer GPUs. It is offered with x86 host CPUs (HGX Rubin NVL8) or with an NVIDIA Vera CPU (HGX Vera Rubin NVL8).
Extreme inference throughput for serving agentic and reasoning models.
130 TB/s of GPU memory bandwidth, 2.1x more than the previous generation.
24 TB/s of NVLink Switch bandwidth across the eight GPUs.
4x more NVFP4 training FLOPS for mixture-of-experts models.
Choose x86 baseboards from OEMs or the 88-core NVIDIA Vera CPU with up to 1.5 TB LPDDR5X.
Bi-directional networking bandwidth for multi-node clusters.
| Configuration | 8× NVIDIA Rubin SXM |
|---|---|
| Host CPU | x86 (OEM-defined) or single-socket NVIDIA Vera (88 Olympus cores, up to 1.5 TB LPDDR5X) |
| GPU memory | 2 TB HBM4 |
| GPU memory bandwidth | 130 TB/s |
| NVLink | Sixth generation, 24 TB/s NVLink Switch bandwidth |
| Networking bandwidth | 1.8 TB/s (bi-directional) |
| Inlet temperature | 45 °C |
| NVFP4 inference | 400 PFLOPS (sparse) |
|---|---|
| NVFP4 training | 270 PFLOPS (dense) |
| FP8/FP6 training | 130 PFLOPS (dense) |
| FP16/BF16 training | 32 PFLOPS (dense) |
| FP32 | 1,040 TFLOPS |
| FP64 | 265 TFLOPS |
| NVFP4 inference | 50 PFLOPS (sparse) |
|---|---|
| NVFP4 training | 35 PFLOPS (dense) |
| FP8/FP6 training | 17.5 PFLOPS (dense) |
| FP16/BF16 training | 4 PFLOPS (dense) |
| FP32 | FP64 | 130 TFLOPS | 33 TFLOPS |
| GPU memory | bandwidth | 288 GB HBM4 | 22 TB/s |
| NVLink bandwidth | 3.6 TB/s |
Liquid-cooled DGX system for training, post-training and inference across every AI workload.
Blackwell Ultra 8-GPU platform for AI reasoning, available in air- and liquid-cooled partner servers.
The proven Blackwell 8-GPU platform for LLM training and high-volume inference.
Tell us your workload and timeline for the NVIDIA HGX Rubin NVL8. We reply within one business day with a configuration, pricing and lead time.