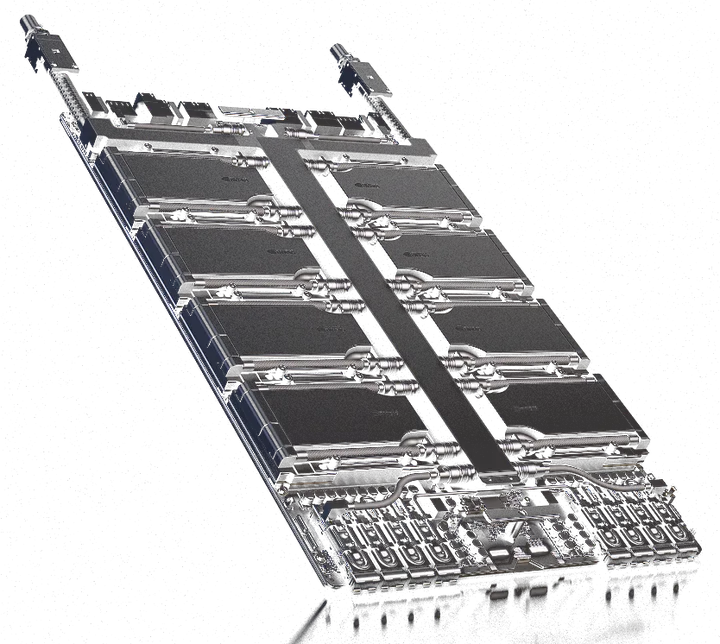
NVIDIA HGX Rubin NVL8
Eight Rubin GPUs on sixth-generation NVLink — the building block for partner servers from Supermicro, ASUS and others.
- GPUs: 8× NVIDIA Rubin
- Interconnect: Sixth-generation NVLink
- Host CPU: NVIDIA Vera or x86 baseboards
Blackwell Ultra 8-GPU platform for AI reasoning, available in air- and liquid-cooled partner servers.
NVIDIA HGX B300 is an eight-GPU Blackwell Ultra baseboard connected by fifth-generation NVLink. It is the GPU engine inside air- and liquid-cooled servers from Supermicro, ASUS and other NVIDIA partners.
Compared with HGX B200 it doubles attention-layer performance and network bandwidth and raises GPU memory, making it the mainstream choice for AI reasoning, inference and training in 2026.
144 PFLOPS with sparsity for efficient low-precision inference.
Faster transformer attention layers than NVIDIA Blackwell.
Large HBM3e capacity across eight GPUs for bigger models and batches.
Double the network bandwidth of HGX B200, via integrated ConnectX-8 SuperNICs.
1.8 TB/s GPU-to-GPU and 14.4 TB/s total NVLink bandwidth.
Available in partner servers in air-cooled and liquid-cooled designs.
| Form factor | 8× NVIDIA Blackwell Ultra SXM |
|---|---|
| Total GPU memory | 2.1 TB HBM3e |
| NVLink | Fifth generation, NVLink 5 Switch |
| NVLink GPU-to-GPU bandwidth | 1.8 TB/s |
| Total NVLink bandwidth | 14.4 TB/s |
| Networking bandwidth | 1.6 TB/s |
| Attention performance | 2x vs. NVIDIA Blackwell |
| FP4 Tensor Core | 144 PFLOPS (sparse) | 108 PFLOPS (dense) |
|---|---|
| FP8/FP6 Tensor Core | 72 PFLOPS |
| INT8 Tensor Core | 3 POPS |
| FP16/BF16 Tensor Core | 36 PFLOPS |
| TF32 Tensor Core | 18 PFLOPS |
| FP32 | 600 TFLOPS |
| FP64 / FP64 Tensor Core | 10 TFLOPS |
Tensor Core figures include sparsity unless noted. Partner servers list HGX B300 with 288 GB of HBM3e per GPU.
Tell us your workload and timeline for the NVIDIA HGX B300. We reply within one business day with a configuration, pricing and lead time.