NVIDIAData Center GPUs

NVIDIA H200 NVL

Hopper-generation PCIe GPU with large HBM3e memory for LLM inference and HPC in air-cooled racks.

  • ArchitectureNVIDIA Hopper
  • Memory141 GB HBM3e
  • Form factorPCIe, dual-slot, NVLink bridge support
  • WorkloadsLLM inference, fine-tuning, HPC
NVIDIA H200 NVL
Overview

About the H200 NVL

NVIDIA H200 NVL is the air-cooled, dual-slot PCIe version of the Hopper H200 GPU. It pairs 141 GB of HBM3e with 4.8 TB/s of bandwidth, giving up to 1.7x faster LLM inference and 1.3x faster HPC than H100 NVL.

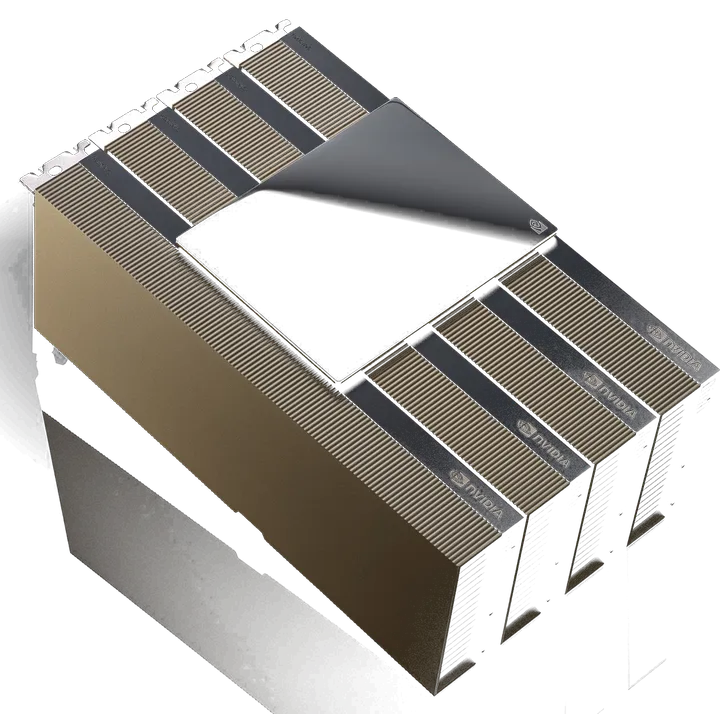
Up to four GPUs can be linked with NVLink bridges at 900 GB/s, and a five-year NVIDIA AI Enterprise subscription is included, making it a strong fit for enterprise racks with standard air cooling.

141 GB HBM3e

Run larger models and datasets without sharding them across GPUs.

4.8 TB/s bandwidth

Feeds memory-bound LLM inference and HPC workloads.

NVLink bridges

2- or 4-way NVLink at 900 GB/s per GPU; up to 8 GPUs per server.

AI Enterprise included

Five-year NVIDIA AI Enterprise subscription with NIM microservices.

Air-cooled

Configurable up to 600 W within standard enterprise cooling.

Confidential computing

Protects sensitive data and models while they are processed.

Specifications

Technical Specifications

Performance

FP6430 TFLOPS
FP64 Tensor Core60 TFLOPS
FP3260 TFLOPS
TF32 Tensor Core835 TFLOPS
BFLOAT16 / FP16 Tensor Core1,671 TFLOPS
FP8 / INT8 Tensor Core3,341 TFLOPS / TOPS

Memory & interconnect

GPU memory141 GB HBM3e
Memory bandwidth4.8 TB/s
Interconnect2- or 4-way NVLink bridge, 900 GB/s per GPU; PCIe Gen5, 128 GB/s

Board & features

Form factorPCIe, dual-slot, air-cooled
Max TDPUp to 600 W (configurable)
MIGUp to 7 instances @ 16.5 GB
Decoders7 NVDEC, 7 JPEG
Confidential computingSupported
Server optionsNVIDIA MGX H200 NVL partner and NVIDIA-Certified Systems with up to 8 GPUs
NVIDIA AI EnterpriseIncluded

Tensor Core figures include sparsity, as published by NVIDIA.

Source: official NVIDIA product information. Specifications are set by the manufacturer and may change. Plan Man confirms the final configuration, availability and lead time in your quote.
Use cases

What it's built for

  • Enterprise LLM inference
  • Retrieval-augmented generation (RAG)
  • Fine-tuning
  • HPC simulation and research
  • Computer vision and speech AI
Plan Man services

Supplied and supported in the UAE

  • Requirement analysis, sizing and bill of materials
  • Genuine supply with manufacturer warranty
  • Rack integration, cabling and onsite deployment
  • Power and liquid cooling planning for dense GPU racks
  • After-sales support, RMA handling and upgrades from Dubai

Get a Quote

Tell us your workload and timeline for the NVIDIA H200 NVL. We reply within one business day with a configuration, pricing and lead time.

Request a Quote